GIZ AI HUMAN
Beyond text. Conversational digital humans interacting face-to-face in real time.
Real-time WebRTC video calls, 180ms debounced double-buffering zero-flicker video swap, and on-premise MuseTalk lipsync.
Giz Models model catalog
Enlarge view ↗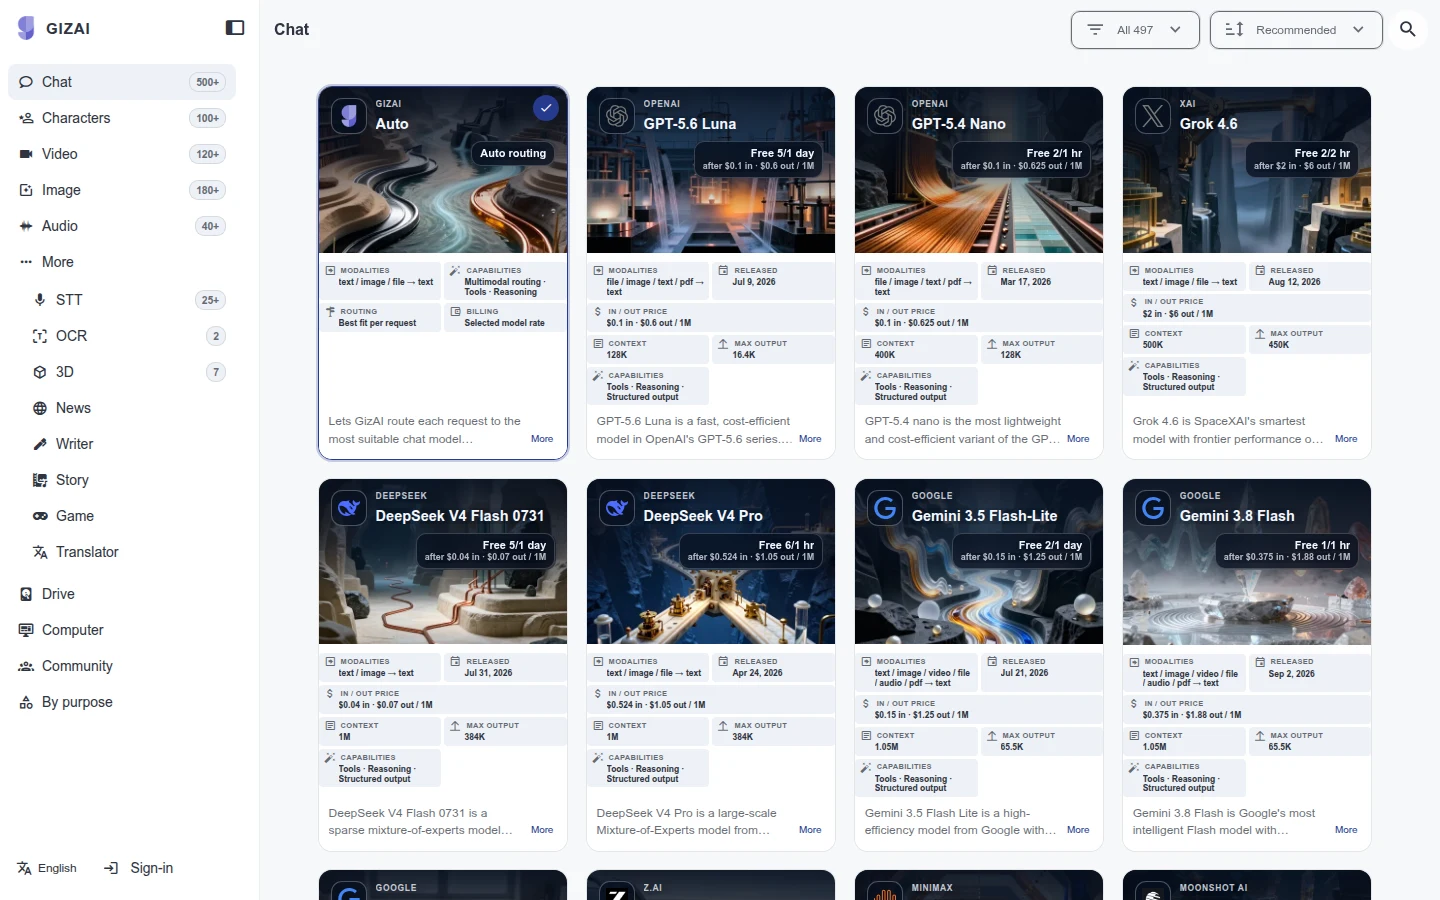
Giz Models model catalog
A catalog for finding models and comparing their descriptions and listed access details. 2026-09-14 · Product screen.
Explore this capability →PRODUCT IN USE
Inspect the product in use.
Check the capture date and sample-data label, then select an image to inspect it. Operating performance, security requirements and customer outcomes are separate acceptance checks.
Giz Models model catalog
Enlarge view ↗Giz Models model catalog
A catalog for finding models and comparing their descriptions and listed access details. 2026-09-14 · Product screen.
Explore this capability →Real-time face-to-face communication surpasses static text chatbots
For customer kiosks, VIP concierge services, and 1:1 online education, text-only chatbots struggle to establish trust and emotional resonance. Existing commercial video generation platforms (such as HeyGen or D-ID) require batch rendering taking 30–120 seconds per response, rendering genuine real-time conversation impossible.
Giz AI Human unites ultra-low-latency WebRTC P2P video streaming, 180ms debounced double-buffering video renderers, and on-premise MuseTalk lipsync workers to deliver seamless, real-time face-to-face interactions identical to an actual video call.
4 Engineering Pillars of Giz AI Human
| Engineering Domain | Giz AI Human Architecture | Operational & Business Value |
|---|---|---|
| WebRTC P2P Ultra-Low Latency | PeerJS mesh network with deterministic peer IDs (giz-${user.id}) |
Sub-200ms round-trip latency for natural, bidirectional audio and video exchanges |
| Zero-Flicker Double-Buffering | useAgentVideoStreams.ts with 180ms debounced background pre-buffering |
Completely eliminates black screen flashes during track swaps for fluid facial expressions |
| On-Premise MuseTalk Lipsync | Real-time landmark alignment workers running on dedicated RTX 5090 fleets | Eliminates external cloud API costs ($/min) while keeping biometric data 100% on-premise |
| Persona & Speech Tuning Studio | AgentCharacterEditorDialog.vue visual editor for appearance, tone, and pitch |
Customizes branded AI bankers, educators, and enterprise brand ambassadors |
3-Stage Real-Time Interaction Pipeline
- Ultra-Fast VAD & Streaming STT: Web Audio API captures microphone speech, streaming audio chunks to on-premise Whisper workers in real time.
- Inference & Audio Synthesis: As soon as LLM inference produces initial tokens, on-premise TTS engines immediately begin speech playback.
- Double-Buffered Lipsync Swap: The browser pre-buffers synthesized video chunks in background elements, smoothly swapping to the active viewport within 180ms.
YOUR NEXT STEP
Bring us the workflow that needs to work.
Start with the files and systems you use today, and the work you want to change.
Ask Giz Agent
Explore capabilities and implementation scope using published product material.