GIZ ML
100% on-premise GPU clusters without external cloud dependencies.
RTX 5090 cluster, WanGP runtime, vLLM dynamic memory sleep/wake, 4GB disk LRU cache, and Whisper speaker diarization.
Architecture illustration
PRODUCT IN USE
Inspect the product in use.
Check the capture date and sample-data label, then select an image to inspect it. Operating performance, security requirements and customer outcomes are separate acceptance checks.
Giz operating settings and status
Enlarge view ↗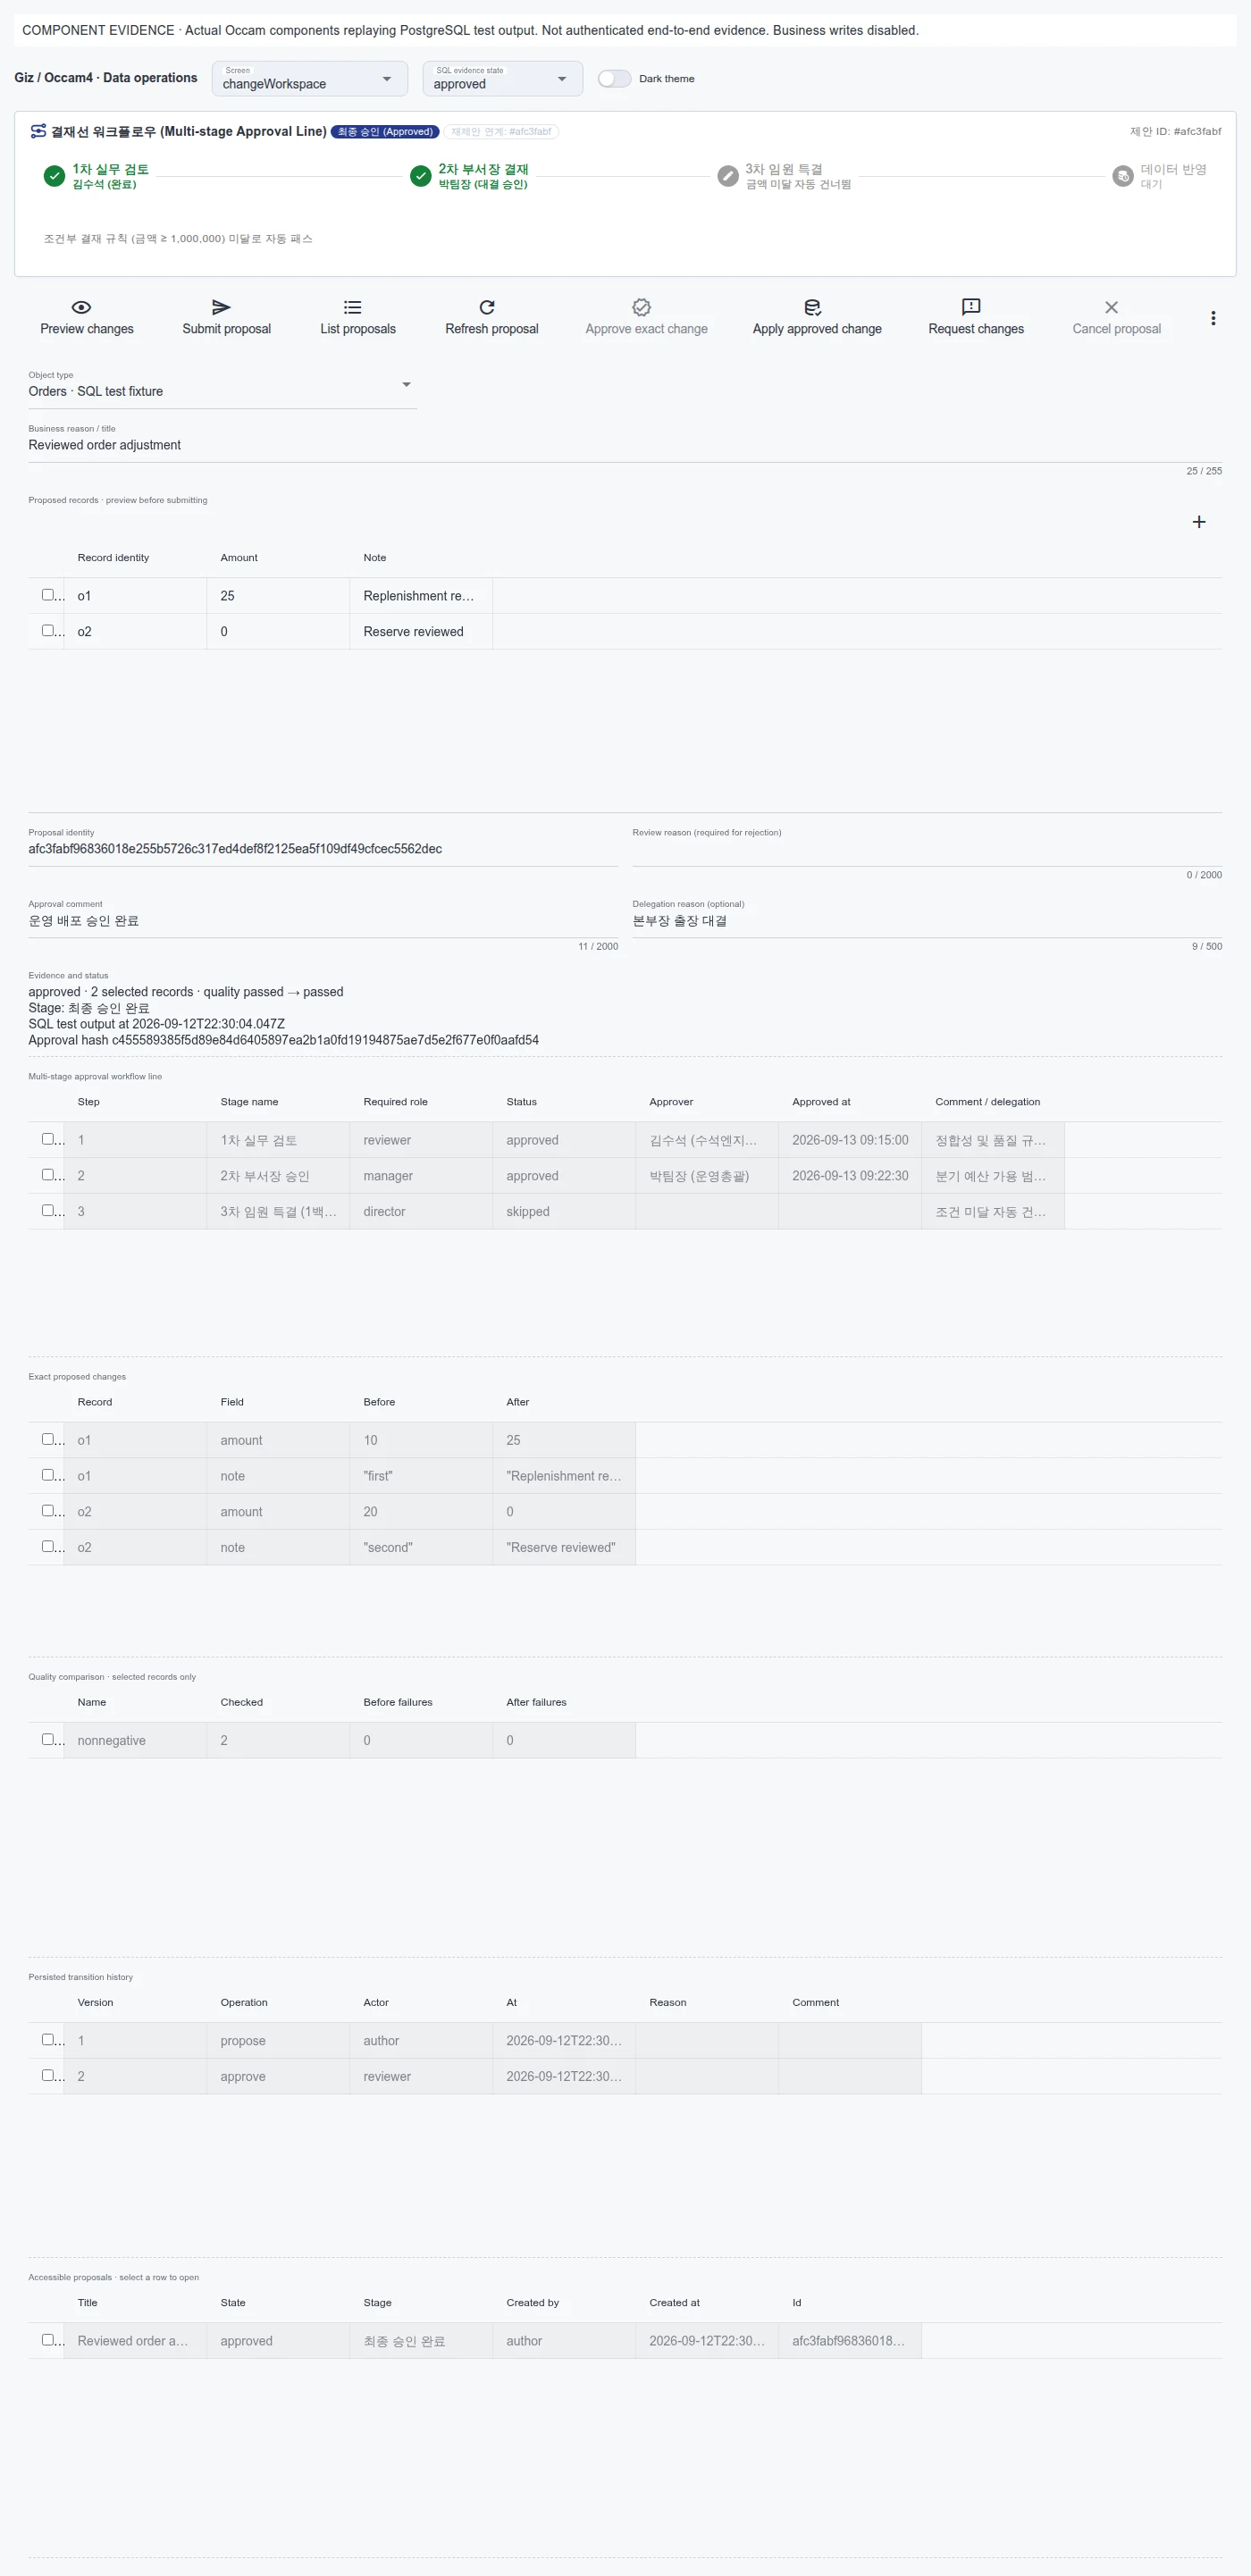
Giz operating settings and status
An administration view of operating settings and status. It is not evidence of air-gapped operation or security certification. 2026-09-13 · Sample data.
Explore this capability →Giz Computer browser terminal
Enlarge view ↗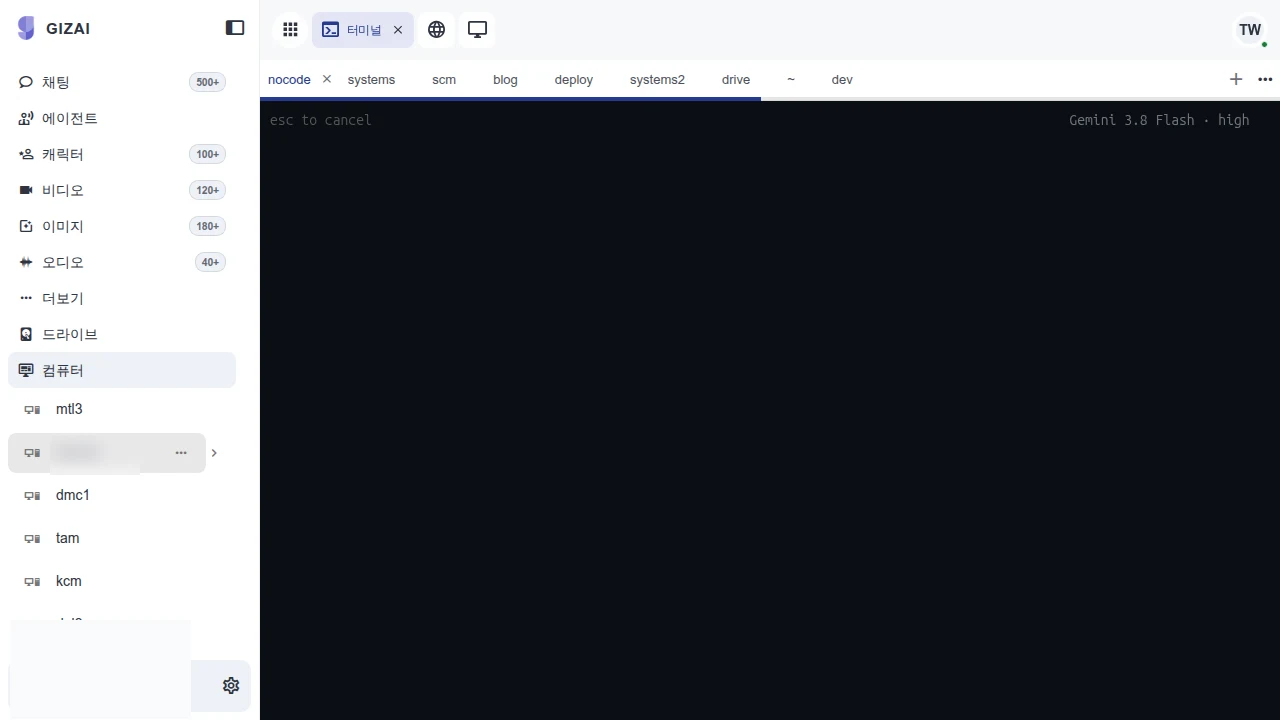
Giz Computer browser terminal
The terminal tab and work area in Computer. Isolation, permissions and recovery are verified through separate execution checks. 2026-09-14 · Product screen.
Explore this capability →Confidential enterprise data and media pipelines cannot be trusted to external clouds
Transmitting sensitive engineering schematics, manufacturing inspection video feeds, unreleased product designs, and executive meeting recordings to third-party AI clouds (such as Runway, Midjourney, or OpenAI) introduces unacceptable enterprise vulnerabilities. Furthermore, escalating API usage fees erode operational profitability as volume scales.
Giz ML is a full-stack machine learning infrastructure powered by on-premise NVIDIA RTX 5090 clusters (ml-dmc1~9, mtl1~4) and the WanGP distributed worker runtime, natively serving ultra-high-definition video generation, real-time lipsync, 50-speaker diarization, and 32k-token document OCR entirely within the enterprise perimeter.
4 Engineering Pillars of Giz ML
| Engineering Domain | Giz ML Architecture | Operational & Business Value |
|---|---|---|
| RTX 5090 WanGP Fleet | NVFP4 quantization backend with NVIDIA VSR super-resolution and HEVC NVENC | Produces 60fps high-fidelity video completely on-premise with zero external API fees |
| vLLM Dynamic Memory Sleep/Wake | Instant VRAM reclamation and process sharing via /sleep?level=1 and /wake_up APIs |
Maximizes GPU hardware utilization by dynamically swapping between OCR and video workers |
| 4GB Disk LRU Cache | High-speed SQLite disk LRU (embeddings.sqlite3, 4,096 MiB) text encoder cache |
Eliminates text encoding compute latency (0ms overhead) across recurring prompt requests |
| High-Capacity Speaker Diarization | Combined faster-whisper large-v3-turbo and pyannote 3.1 pipeline |
Separates and transcribes up to 50 concurrent meeting participants with millisecond timestamps |
7 AI Media Pipelines Running In-House
- Video Generation & Frame Interpolation: LTX-Video foundation generation with ComfyUI RIFE 60fps interpolation.
- Real-time Digital Human Lipsync: MuseTalk and SoulX landmark synthesis from a single portrait and audio track.
- 50-Speaker Meeting Diarization: Multi-speaker discussion separation and timestamped automated transcript generation.
- 32k-Token Vision Document OCR: OvisOCR2 structured markdown extraction for multi-column papers, tables, and LaTeX.
- Speech Synthesis & BGM Composition: Expressive OmniVoice Korean/English TTS and Stable Audio 3 generation.
Giz AI Gateway · Sovereign AI Platform · Giz AI Human
YOUR NEXT STEP
Bring us the workflow that needs to work.
Start with the files and systems you use today, and the work you want to change.